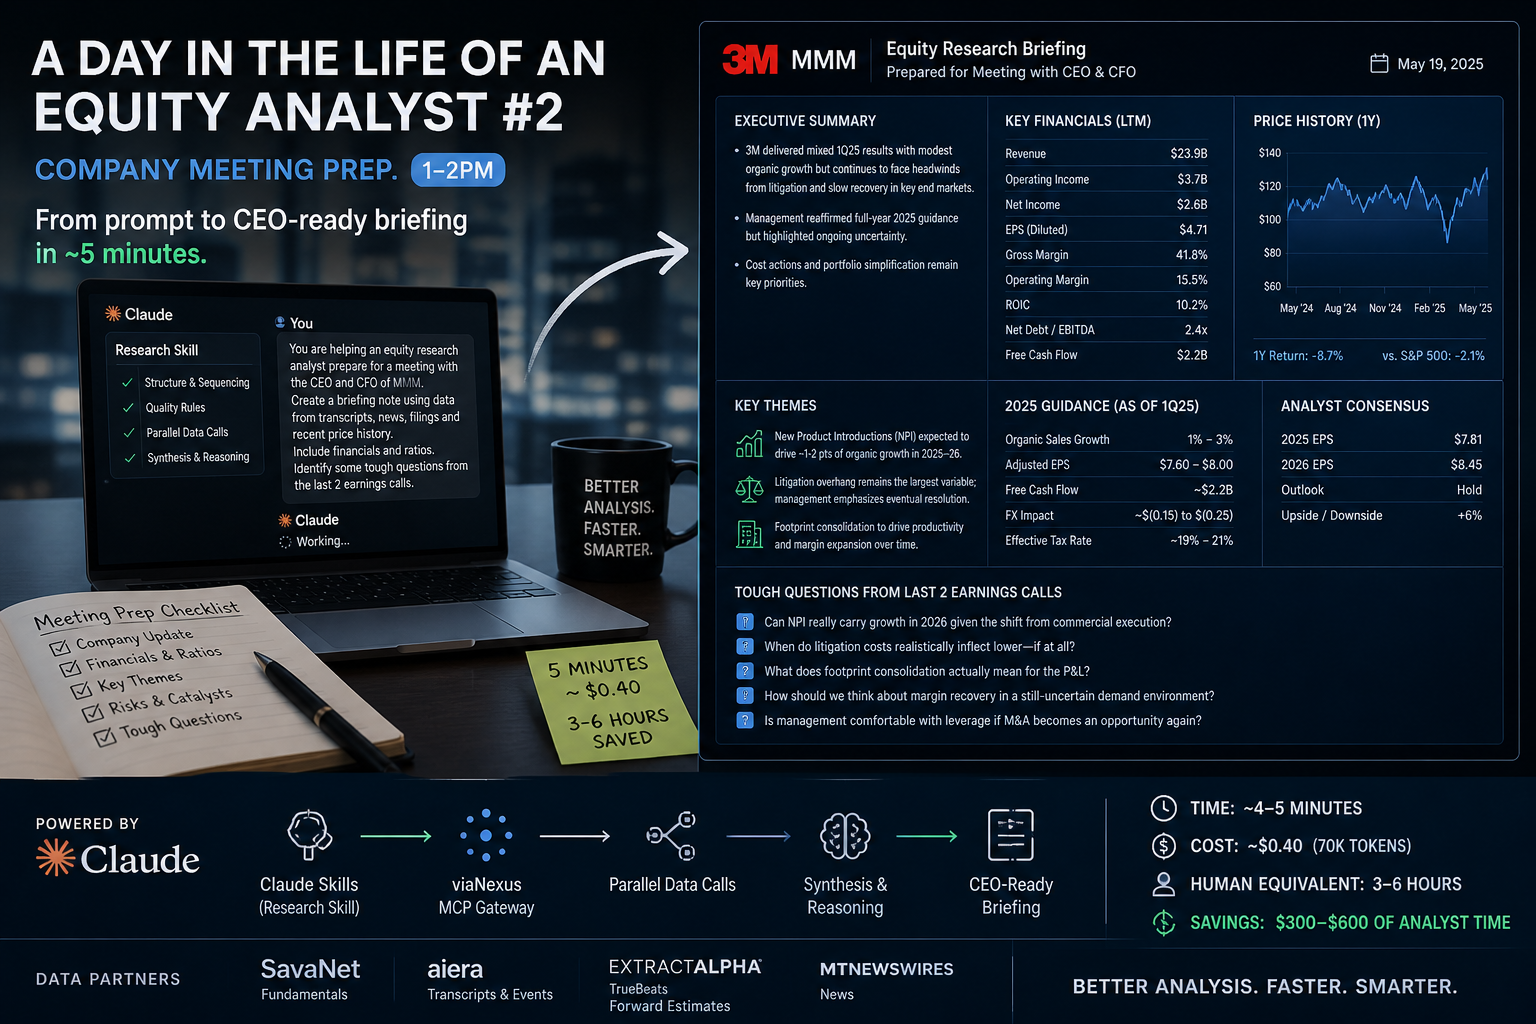
𝐂𝐨𝐦𝐩𝐚𝐧𝐲 𝐌𝐞𝐞𝐭𝐢𝐧𝐠 𝐏𝐫𝐞𝐩. 𝟏-𝟐𝐩𝐦
One of the most intensive tasks - prep for a meeting with company management. This works for both the sell side (covered company) or the buyside (portfolio company).
The prompt was just this. “𝘠𝘰𝘶 𝘢𝘳𝘦 𝘩𝘦𝘭𝘱𝘪𝘯𝘨 𝘢𝘯 𝘦𝘲𝘶𝘪𝘵𝘺 𝘳𝘦𝘴𝘦𝘢𝘳𝘤𝘩 𝘢𝘯𝘢𝘭𝘺𝘴𝘵 𝘱𝘳𝘦𝘱𝘢𝘳𝘦 𝘧𝘰𝘳 𝘢 𝘮𝘦𝘦𝘵𝘪𝘯𝘨 𝘸𝘪𝘵𝘩 𝘵𝘩𝘦 𝘊𝘌𝘖 𝘢𝘯𝘥 𝘊𝘍𝘖 𝘰𝘧 𝘔𝘔𝘔. 𝘤𝘳𝘦𝘢𝘵𝘦 𝘢 𝘣𝘳𝘪𝘦𝘧𝘪𝘯𝘨 𝘯𝘰𝘵𝘦 𝘧𝘰𝘳 𝘵𝘩𝘦 𝘮𝘦𝘦𝘵𝘪𝘯𝘨, 𝘶𝘴𝘪𝘯𝘨 𝘥𝘢𝘵𝘢 𝘧𝘳𝘰𝘮 𝘵𝘳𝘢𝘯𝘴𝘤𝘳𝘪𝘱𝘵𝘴, 𝘯𝘦𝘸𝘴, 𝘧𝘪𝘭𝘪𝘯𝘨𝘴 𝘢𝘯𝘥 𝘳𝘦𝘤𝘦𝘯𝘵 𝘱𝘳𝘪𝘤𝘦 𝘩𝘪𝘴𝘵𝘰𝘳𝘺. 𝘐𝘯𝘤𝘭𝘶𝘥𝘦 𝘧𝘪𝘯𝘢𝘯𝘤𝘪𝘢𝘭𝘴 𝘢𝘯𝘥 𝘳𝘢𝘵𝘪𝘰𝘴. 𝘪𝘥𝘦𝘯𝘵𝘪𝘧𝘺 𝘴𝘰𝘮𝘦 𝘵𝘰𝘶𝘨𝘩 𝘲𝘶𝘦𝘴𝘵𝘪𝘰𝘯𝘴 𝘧𝘳𝘰𝘮 𝘵𝘩𝘦 𝘭𝘢𝘴𝘵 2 𝘦𝘢𝘳𝘯𝘪𝘯𝘨𝘴 𝘤𝘢𝘭𝘭𝘴".
What came back in 5 minutes is the briefing attached below.
𝗜 𝘄𝗮𝘀 𝗯𝗹𝗼𝘄𝗻 𝗮𝘄𝗮𝘆. But the interesting part is how it was built. I asked Claude and her was the response:
"viaNexus MCP Tools The foundational data layer. I used the viaNexus:fetch tool across eight separate dataset calls — QUOTE, STOCK_STATS_US, COMPANY_DESCRIPTIONS, SUMMARY_NORMALIZED_FINANCIALS (quarterly and annual), NORMALIZED_FUNDAMENTALS, TRUEBEATS_EPS_REVENUE_FORECASTS, EVENTS_CALENDAR, and HISTORICAL_EVENTS_TRANSCRIPTS — plus MT Newswires for analyst coverage. All fetched in sequence to populate every data point in the report with live, sourced figures rather than recalled knowledge.The Equity Research Report Skill (/mnt/skills/user/equity-research-report/SKILL.md) A custom skill you built in a prior session. It defined the exact data fetch sequence, the report structure (12 sections), formatting rules (human-readable numbers, no invented figures), and quality checks. Without reading that skill first, the report would have been structurally different and likely missed several datasets.Transcript Parsing via Bash The AIERA transcript files for Q4 2025 (767 entries, ~1MB) and Q3 2025 (719 entries) were too large for direct context. I used bash_tool with Python to decompress and navigate the JSON structure, extract the full transcript text, locate the Q&A sections by position, and read specific 8,000-character windows to surface the key management exchanges — the Jeff Sprague footprint question, Steve Tusa on litigation costs, Julian Mitchell on macro vs. self-help, Scott Davis on NPI quality.The Frontend Design Skill (/mnt/skills/public/frontend-design/SKILL.md) Governed the visual output. Rather than producing a plain markdown document, I read the design skill and applied it to produce a production-grade HTML briefing with a considered aesthetic — Playfair Display / IBM Plex Sans type pairing, a dark masthead with red accent, structured color-coded sections, bull/bear boxes, and a distinct question format with source tagging.Synthesis and Judgment The data and transcripts provided the raw material, but constructing the 11 questions, the bull/bear cases, and the analyst summary required integrating across sources — connecting a pricing comment in the Q3 call to a margin guidance assumption in Q4, or linking the Wolfe Research target raise to the RBC bear case in the same week. That analytical layer sits outside any single tool.
In short: the skill files told me what to build and how to structure it, the MCP tools provided the data, bash gave me access to the transcripts, and the synthesis layer turned it into something useful for an actual meeting."
The "reasoning" is getting really powerful, and exceeds what most analysts would do coming to this company raw. A seasoned analyst covering the company might say otherwise. Connecting guidance shifts, analyst positioning, and management commentary into questions you’d actually ask in the room. ie
▶️ Can NPI really carry growth in 2026 given the shift from commercial execution?
▶️ When do litigation costs realistically inflect lower—if at all?
▶️ What does footprint consolidation actually mean for the P&L?
Now here’s the part that should make people pause - the estimated cost of this report (excluding the source content): Token Usage as estimated by Claude is estimated as per below:
| Component | Approx. Tokens |
|---|---|
| System prompt + memory context | ~8,000 |
| Skill files read (equity research + frontend design) | ~4,000 |
| MCP data responses (8 dataset fetches) | ~15,000 |
| Transcript parsing output (bash tool reads) | ~25,000 |
| Report generation (HTML output) | ~12,000 |
| Tool calls, conversation overhead | ~5,000 |
| Total estimate | ~70,000 tokens |
The approximate Cost Using Claude Sonnet 4.6 API pricing as a reference point:
| Tokens | Rate | Cost | |
|---|---|---|---|
| Input | ~55,000 | $3 / 1M | ~$0.17 |
| Output | ~15,000 | $15 / 1M | ~$0.23 |
| Total | ~$0.40 |
The data behind it came from real partners—normalized, permissioned, reliable: SavaNet for fundamentals, Aiera for transcripts & events, ExtractAlpha TrueBeats for forward estimates and MT Newswires for news - all flowing through and normalized by viaNexus. All accessible from a single prompt.
The takeaway isn’t “AI is impressive.” It’s that the architecture matters.
No specialized copilot. No heavy desktop. No brittle workflows. No unreliable, unlicensed data scraped from the internet!
Just Claude + Skills + permissioned data—configured once, usable every time.
Try it for your self - with a free trial, or your subscription, connect the viaNexus MCP: https://vast-mcp.blueskyapi.com/mcp